Find the right tool
Say what you want to do in your own words, in English or Arabic, and we will search the AI tools for it.
45 tools found · showing 12
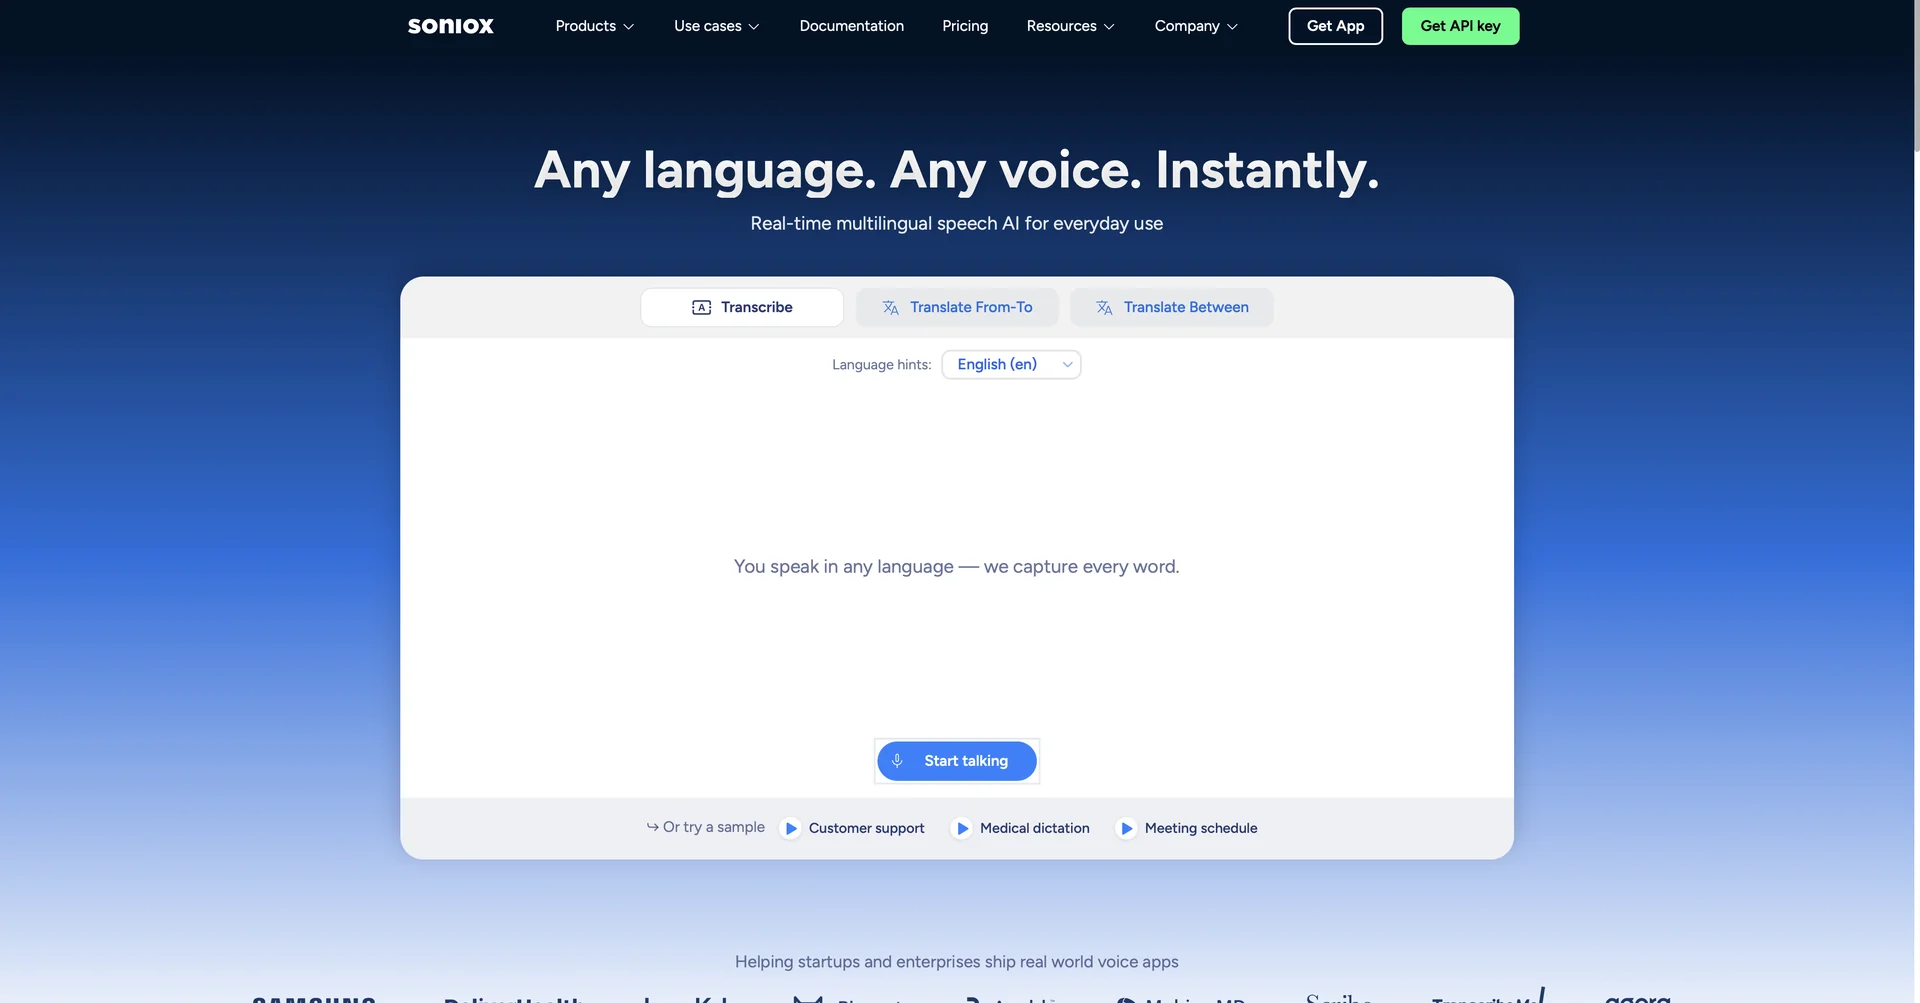
Soniox Speech-to-Text
Free TrialTranscribe, diarize, and translate live global conversations.
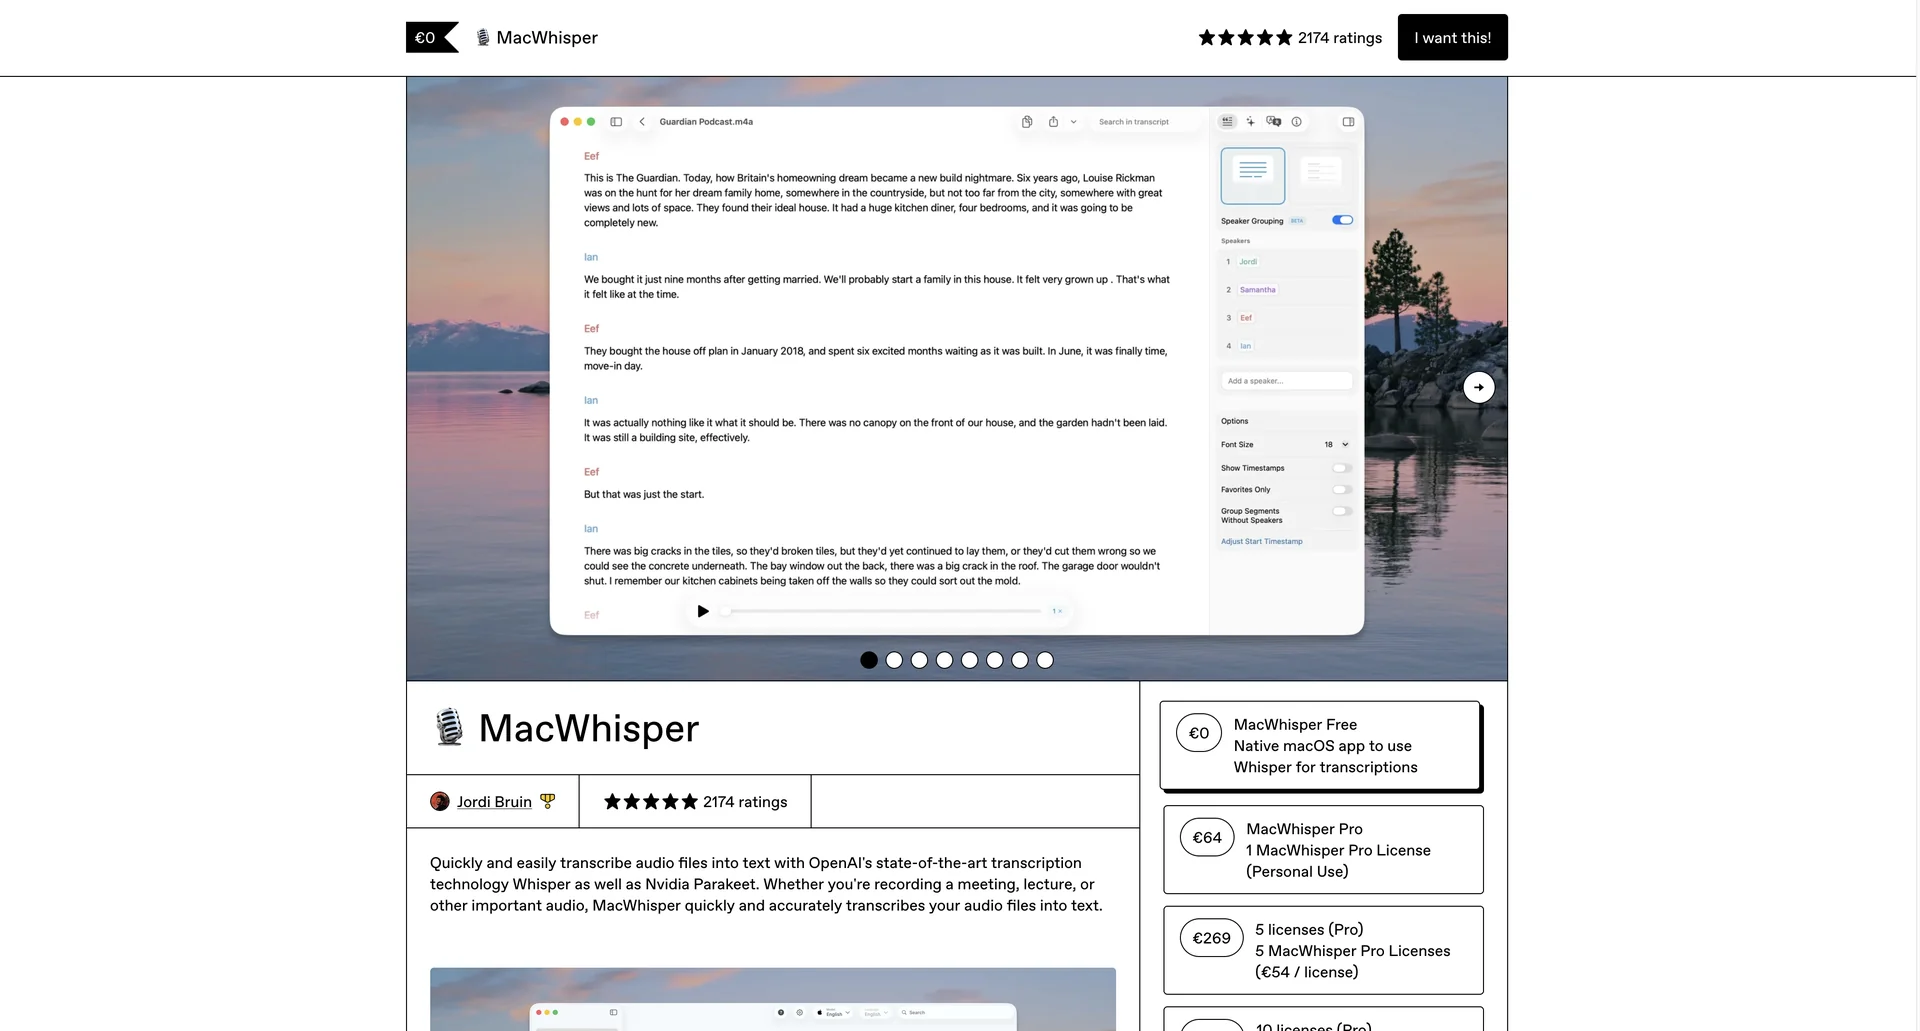
MacWhisper
PaidTranscribe audio files into text with AI, all on your device.
Amical
Free TrialAmical is a voice dictation and speech-to-text tool that allows users to speak instead of typing, with the option to run AI models locally on the device or use cloud-based models.
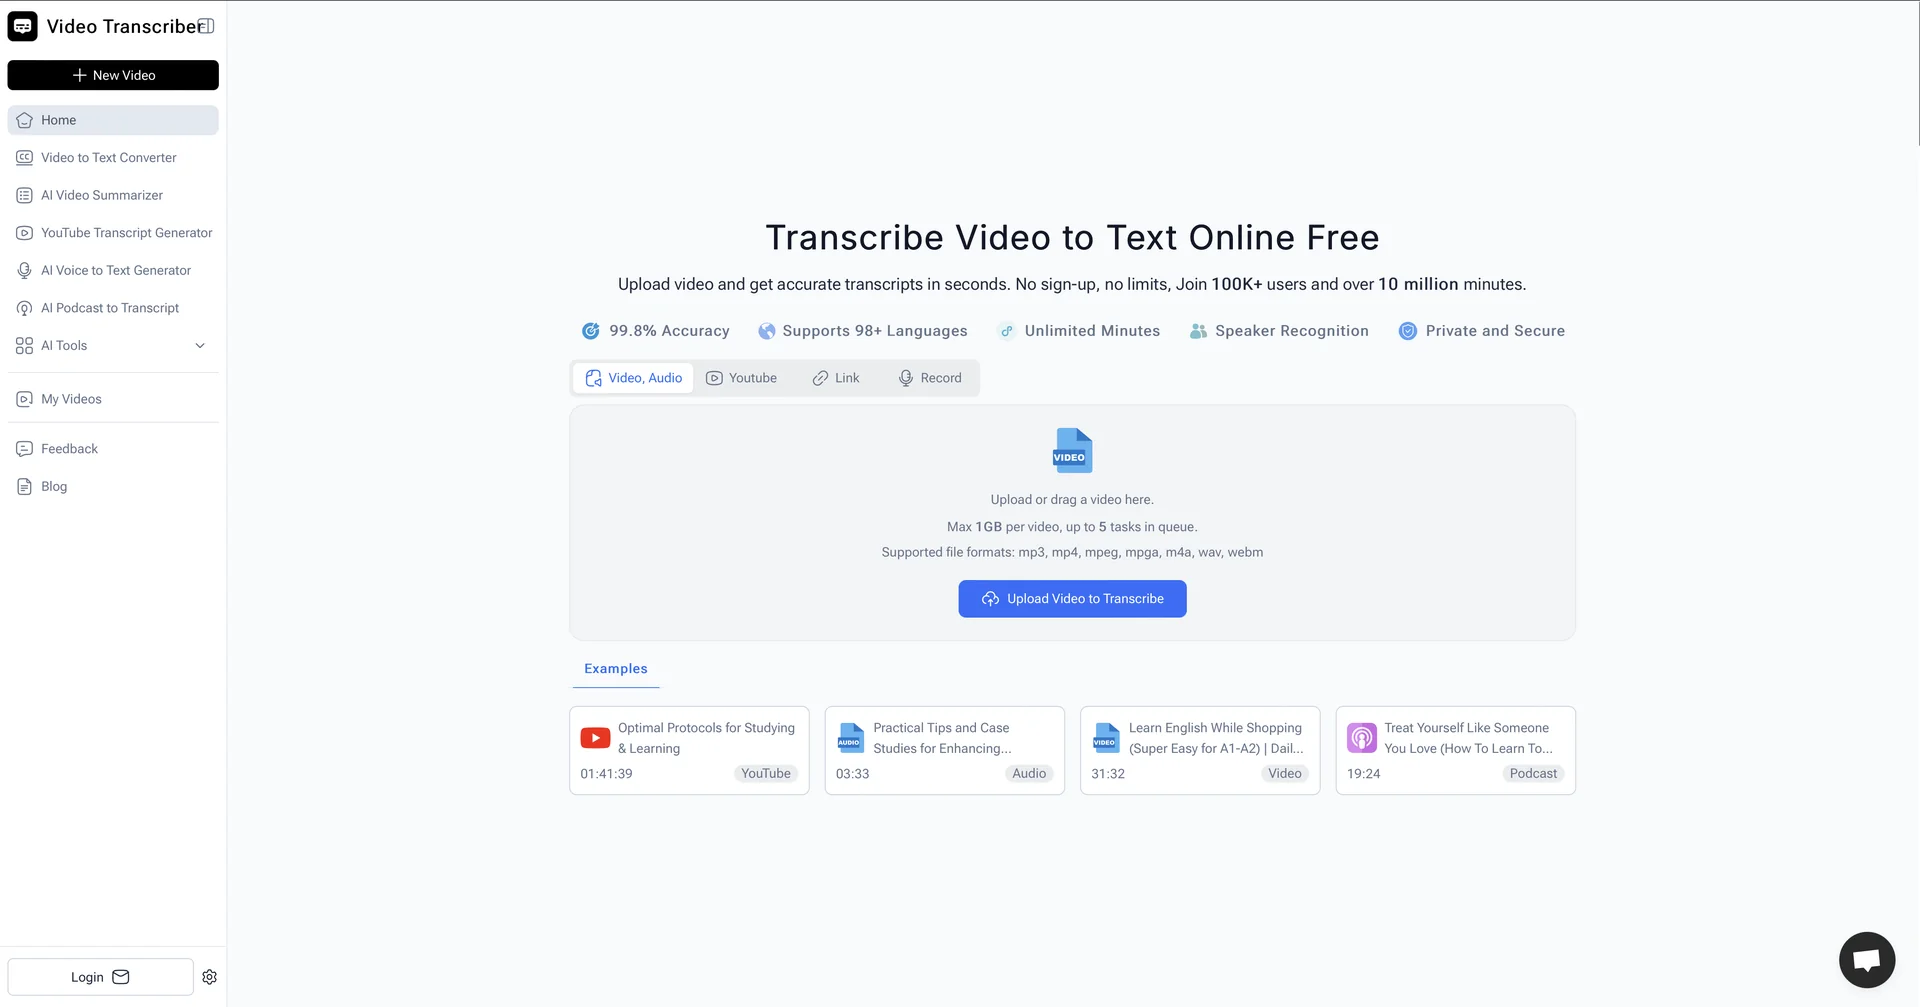
Video Transcriber AI
Free TrialTranscribe video to text online free
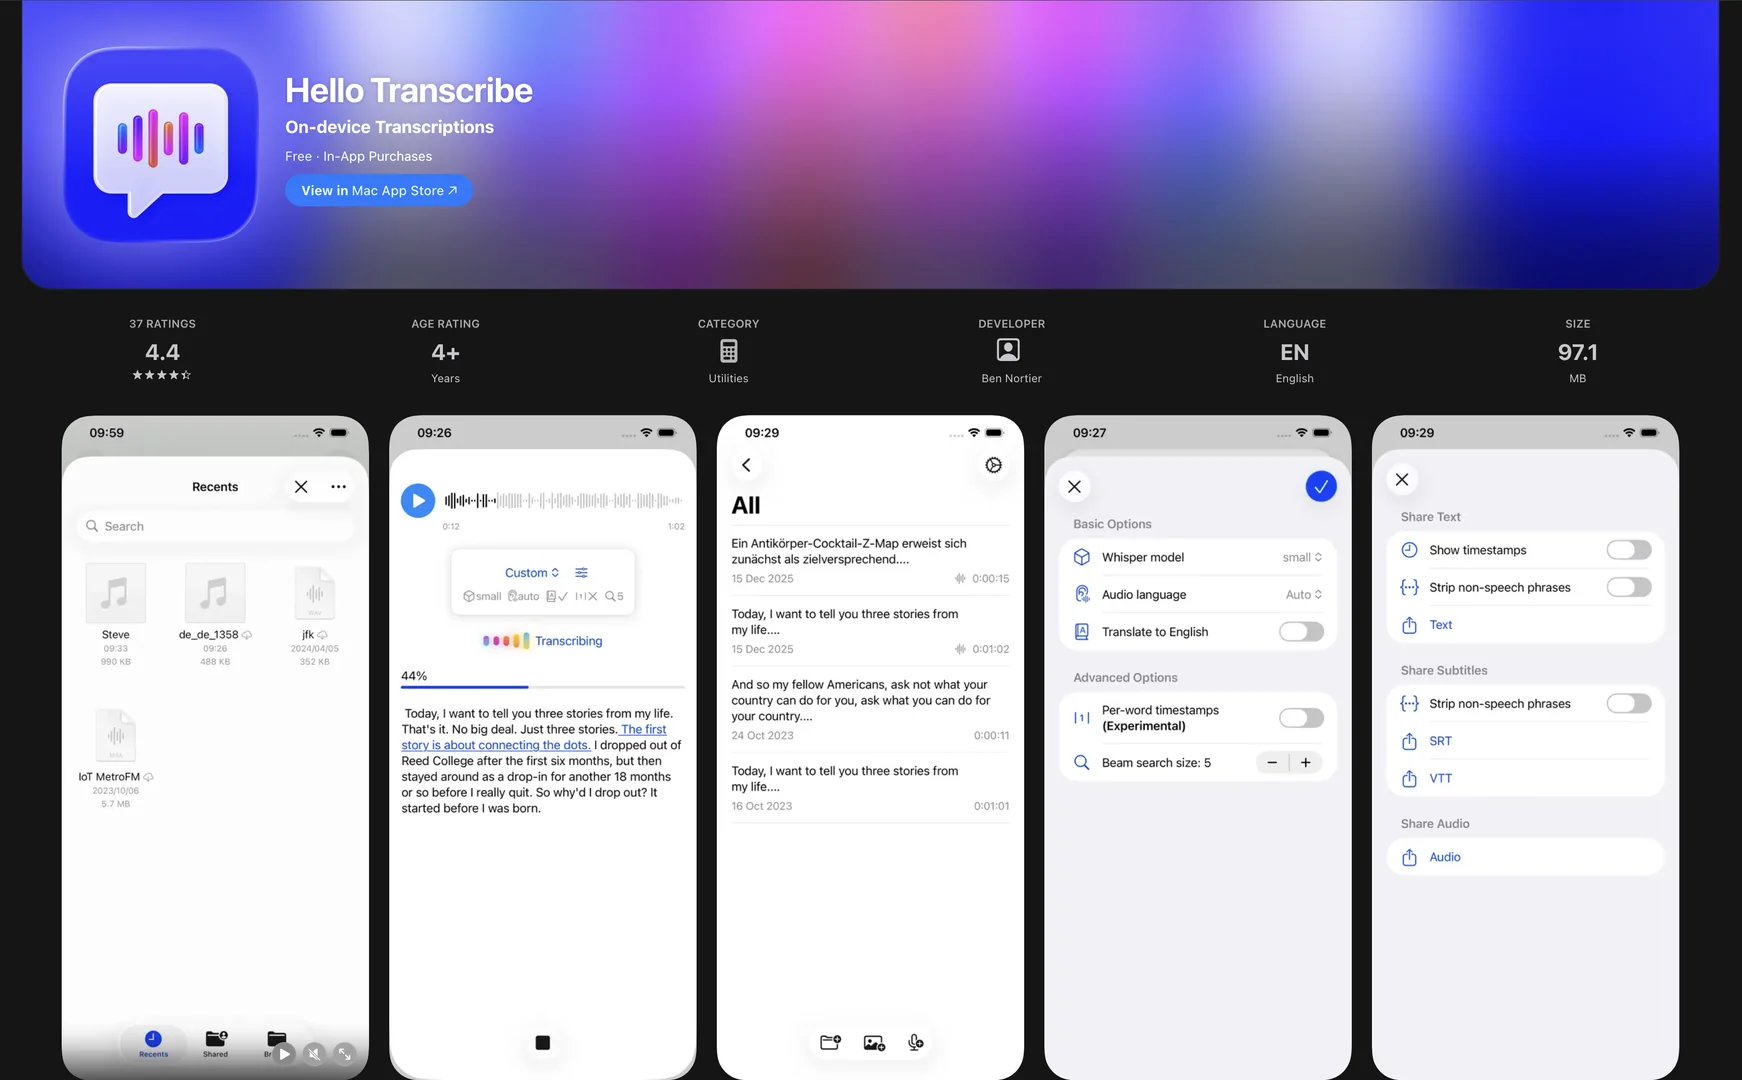
Hello Transcribe
Free TrialAudio files transcribed to text

Deepgram
Free TrialDeepgram is an artificial intelligence platform specializing in voice technologies, presented as the primary engine of the Voice AI economy. It provides companies and developers with high-precision software interfaces for speech-to-text conversion, text-to-speech conversion, and building intelligent voice agents that operate in real time or through batch processing. The platform relies on advanced models that are highly accurate, fast, and realistic, with lower operating costs compared to traditional solutions, and supports multiple deployment models including cloud and self-hosted to meet the requirements of different organizations.

Azure AI Speech Studio
Free TrialAzure AI Speech Studio is Microsoft's cloud-based creative lab for developing speech technologies. The platform offers comprehensive solutions that include speech-to-text conversion with amazing accuracy and text-to-speech conversion using more than 400 neural voices in 140 languages. In 2026, advanced video translation features and personal voice cloning were integrated, requiring only a 60-second voice sample to create a digital replica of the user's voice.

ai coustics
Free Trialai-coustics is a platform specializing in real-time audio enhancement and processing, focused on improving the quality of audio signals before they enter AI systems such as speech-to-text (STT) or audio processing in Voice AI applications. It functions as an Audio Reliability Layer that cleans up audio, removes noise, and improves speech clarity with an extremely low latency.
Gladia
Free TrialGladia relies on an AI-powered audio infrastructure that enables companies and developers to record audio and video, transcribe speech to text, and then enrich and analyze the audio data through a single API.
Notta
Free TrialNotta uses artificial intelligence to record meetings and conversations, transcribe speech into text, analyze the content, generate automatic summaries and action items, and extract key takeaways. The platform offers live audio and video recording, along with real-time transcription, speaker recognition, and translation.

Soniox
Free TrialSoniox is an audio platform that provides application programming interfaces (APIs) for speech processing, speech-to-text conversion, text-to-speech conversion, and speech translation, with support for more than 60 languages. The platform enables real-time or asynchronous speech transcription and operates on a usage-based pricing model, whereby users pay for the Speech-to-Text and Text-to-Speech services they actually use. Soniox offers the stt-rt-v5 model for real-time transcription—which is the currently active model according to the official documentation—as well as the stt-async-v5 model for asynchronous processing of audio files. The stt-rt-v5 model offers improvements in recognition accuracy, speaker separation, spoken language identification, real-time translation, faster speech termination, context handling, and recognition of structured data such as numbers, dates, email addresses, names, addresses, and codes.

Scribewave AI
Free TrialA tool for for audio and video files transcription.